Does Range Include Outliers? The Hidden Truth Behind Statistical Distributions
Table of Contents
- The Complete Overview of Statistical Range and Outlier Inclusion
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: If outliers are included in the range, how can I adjust for them?
- Q: Are there industries where range is preferred despite outliers?
- Q: Can outliers ever be useful in range calculations?
- Q: Why do some textbooks say range is "not robust" but still teach it?
- Q: How do I decide whether to include outliers in my range?
The question does range include outliers cuts to the heart of statistical interpretation—where raw numbers meet real-world decision-making. At first glance, the answer seems straightforward: range is simply the difference between maximum and minimum values in a dataset. But dig deeper, and the nuances emerge. Outliers, those extreme values that deviate dramatically from the rest, can distort this measure in ways that mislead analysts, policymakers, and researchers alike. While textbooks often gloss over this detail, the practical consequences are profound—from skewed business metrics to flawed scientific conclusions.
Consider a dataset tracking monthly sales for a retail chain. One month, a single store experiences an unprecedented surge due to a viral marketing campaign, creating an outlier. The raw range—calculated as the difference between this peak month and the lowest-performing month—suddenly ballooned by 30%. Yet this inflated range obscures the typical performance patterns that matter more to long-term strategy. The same principle applies in finance, where a single rogue trade can artificially stretch the range of daily returns, making risk assessments appear far more volatile than they truly are.
This tension between simplicity and accuracy lies at the core of statistical debates. The range, as a measure of dispersion, was never designed to be robust against outliers—but its vulnerability raises critical questions. Should analysts adjust for outliers when calculating range? Or does doing so introduce arbitrary subjectivity? The answer depends on context, purpose, and the trade-offs between precision and practicality.
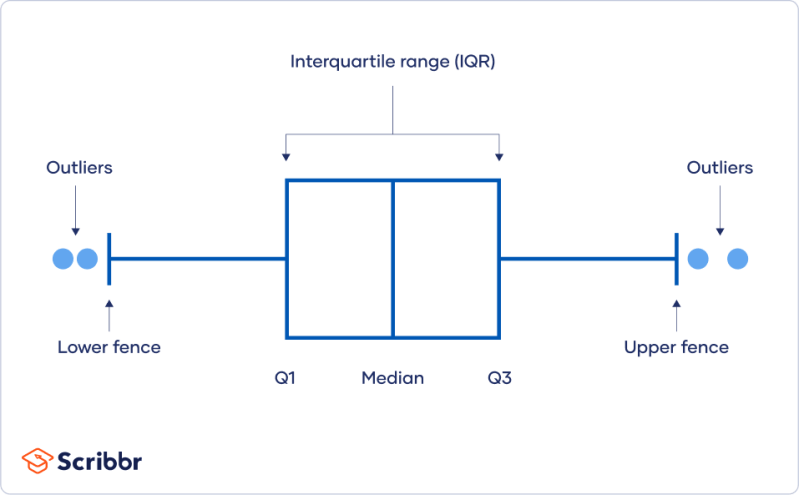
The Complete Overview of Statistical Range and Outlier Inclusion
The statistical range, defined as the difference between the maximum and minimum values in a dataset, is one of the most intuitive yet contentious measures of variability. Its simplicity makes it accessible for quick assessments, but this very feature becomes its Achilles’ heel when outliers are present. Unlike more sophisticated measures such as standard deviation or interquartile range (IQR), the range offers no built-in safeguards against extreme values. This lack of resilience means that does range include outliers isn’t just a theoretical question—it’s a practical dilemma with tangible consequences for data-driven fields.The core issue stems from the range’s reliance on two data points: the highest and lowest values. In datasets with outliers, these values may not reflect the underlying distribution’s central tendency or typical spread. For example, in a study of household incomes, a billionaire’s presence could inflate the range to millions, masking the fact that 90% of households earn between $30,000 and $80,000. This distortion isn’t just academic; it can lead to misallocated resources, flawed policy recommendations, or even legal disputes where financial data is contested.
Historical Background and Evolution
The concept of range as a measure of dispersion emerged in the late 19th century as statisticians sought simple, interpretable tools for summarizing data. Early statisticians like Karl Pearson and Francis Galton focused on central tendency (mean, median), but the need for a complementary measure of spread became clear. The range, with its straightforward calculation, filled this gap—especially in fields like quality control and early social sciences, where datasets were often small and exploratory.However, as datasets grew larger and more complex in the 20th century, the limitations of the range became apparent. Pioneers like George Box and John Tukey later introduced robust alternatives like the IQR, which explicitly excludes outliers by focusing on the middle 50% of data. This evolution reflects a broader shift in statistics: from descriptive simplicity to rigorous robustness. The question does range include outliers thus mirrors a deeper tension between tradition and innovation in data analysis.
The rise of computational power in the late 20th century further highlighted the range’s weaknesses. With big data, outliers—once rare anomalies—became more frequent and detectable. Fields like finance and cybersecurity now grapple with datasets where outliers aren’t errors but meaningful signals (e.g., fraudulent transactions). Yet, even in these domains, the range persists in some applications, not because it’s ideal, but because it’s familiar and computationally efficient.
Core Mechanisms: How It Works
At its most basic, the range is calculated by subtracting the smallest value in a dataset from the largest:Range = Max – Min.
This operation is sensitive to outliers because it depends entirely on the two extreme values. For instance, in a sample of exam scores where 95% of students scored between 70 and 85, but two students scored 30 and 99, the range becomes 69. Yet the true spread of most scores is just 15 points—a discrepancy that can mislead educators assessing performance consistency.
The vulnerability arises because outliers can be:
1. Genuine extremes (e.g., a record-breaking sales month),
2. Data errors (e.g., a misrecorded value), or
3. Structural anomalies (e.g., a new product launch distorting historical trends).
When does range include outliers become critical is when these extremes are not representative of the dataset’s core behavior. For example, in environmental science, a single extreme temperature reading in a climate dataset could artificially inflate the range, obscuring long-term trends. The solution? Context matters. If the outlier is a one-time event (e.g., a natural disaster), including it may be justified. If it’s an error, excluding it is prudent. But the range offers no mechanism to distinguish between these cases.
Key Benefits and Crucial Impact
Despite its limitations, the range remains a valuable tool in specific contexts. Its primary advantage is simplicity: it requires no complex calculations, making it ideal for rapid assessments or educational settings where students are learning foundational statistics. In manufacturing, for example, quality control teams might use range to quickly identify whether a production batch’s dimensions fall within acceptable tolerances. Here, outliers could signal defects, and the range’s sensitivity becomes a feature, not a bug.The range’s impact extends to decision-making in high-stakes environments where speed is critical. Financial traders, for instance, might monitor the daily range of stock prices to gauge volatility. While outliers (e.g., flash crashes) can distort this measure, traders often accept the trade-off because the range provides an immediate, actionable snapshot. The key is recognizing that does range include outliers isn’t a binary yes or no—it’s a question of whether the distortion aligns with the decision’s goals.
> "The range is like a ruler stretched between two points—useful for measuring distance, but useless if one end is broken. Statistics should never be about the tool, but about the question it answers." — Dr. Nancy Gore, Professor of Biostatistics, Harvard University
Major Advantages
- Computational Efficiency: Requires only two values (max/min), making it faster to calculate than standard deviation or IQR, especially in large datasets.
- Intuitive Interpretation: Easy to explain to non-technical stakeholders (e.g., "The range is $100, meaning prices vary from $50 to $150").
- Useful for Control Limits: In process control (e.g., Six Sigma), range helps set thresholds for acceptable variability.
- Robust for Small Samples: With fewer than 20 data points, the range can be more reliable than other measures prone to sampling error.
- Historical Precedent: Deeply embedded in legacy systems and regulatory standards (e.g., financial reporting, environmental monitoring).
Comparative Analysis
| Metric | Outlier Sensitivity |
|---|---|
| Range (Max – Min) | Highly sensitive; outliers directly inflate/deflate the value. |
| Interquartile Range (IQR, Q3 – Q1) | Robust; excludes the top and bottom 25% of data, minimizing outlier impact. |
| Standard Deviation | Moderately sensitive; outliers increase variance but less dramatically than range. |
| Mean Absolute Deviation (MAD) | Less sensitive than range but more than standard deviation; averages absolute deviations from the mean. |

Future Trends and Innovations
The future of statistical measures like range will likely be shaped by two forces: automation and domain-specific adaptation. As machine learning models increasingly handle data preprocessing, automated outlier detection (e.g., using isolation forests or DBSCAN) may prompt statisticians to rethink how range is applied. Instead of blindly calculating Max – Min, algorithms could flag outliers and either exclude them or adjust the range dynamically based on context.Another trend is the rise of hybrid metrics that combine the simplicity of range with robustness. For example, a "trimmed range" could exclude the top and bottom x% of values, offering a middle ground between raw range and IQR. In healthcare analytics, where outliers might represent critical cases (e.g., rare diseases), such adaptations could bridge the gap between descriptive statistics and actionable insights.
Ultimately, the question does range include outliers will evolve from a binary concern to a configurable parameter—one where analysts can toggle sensitivity based on the data’s nature and the question’s intent. This shift reflects a broader movement toward context-aware statistics, where tools adapt to the problem rather than the problem adapting to the tool.
Conclusion
The range’s relationship with outliers is a microcosm of broader challenges in data science: balancing simplicity with accuracy, tradition with innovation. While the range remains a useful starting point, its limitations—particularly its susceptibility to distortion by extreme values—demand careful consideration. The answer to does range include outliers isn’t universal; it depends on whether the outliers are meaningful signals or noise, and whether the range’s simplicity outweighs its potential for misdirection.For practitioners, the takeaway is clear: never rely solely on range when outliers are present. Pair it with robust alternatives like IQR or visualize the data to assess distribution shape. For educators and tool developers, the conversation should continue—exploring how statistical measures can evolve to meet the demands of an era where data is both abundant and ambiguous. In the end, the range’s enduring relevance lies not in its perfection, but in its ability to spark critical questions about what we choose to measure—and why.
Comprehensive FAQs
Q: If outliers are included in the range, how can I adjust for them?
The most common adjustments are:
1. Use the Interquartile Range (IQR): Excludes the top and bottom 25% of data, focusing on the central 50%.
2. Trimmed Range: Remove a fixed percentage (e.g., 5%) from both ends before calculating range.
3. Modified Range: Subtract a multiple of the standard deviation from max/min to "shrink" the range artificially.
For example, a "10% trimmed range" would exclude the lowest 10% and highest 10% of values before computing Max – Min.
Q: Are there industries where range is preferred despite outliers?
Yes, primarily in fields where:
Q: Can outliers ever be useful in range calculations?
Absolutely. Outliers can reveal:
Q: Why do some textbooks say range is "not robust" but still teach it?
Textbooks emphasize the range for three reasons:
1. Foundational Learning: It’s the simplest measure of dispersion, teaching students about variability before introducing complex concepts.
2. Historical Context: Early statisticians used range before robust alternatives (IQR, MAD) were developed.
3. Practicality: In many real-world scenarios (e.g., quality control), range is sufficient for initial screening, even if later analysis uses more sophisticated methods.
The "not robust" label serves as a caution, not a dismissal—range is a tool, not a universal solution.
Q: How do I decide whether to include outliers in my range?
Ask these questions:
1. Is the outlier an error? If yes, correct or remove it.
2. Does the outlier represent a meaningful extreme? If yes, include it but pair range with other metrics (e.g., median, IQR).
3. What’s the purpose of the analysis? If the goal is to understand typical behavior, exclude outliers. If it’s to capture all possible variation, include them.
4. Are there domain-specific conventions? Some fields (e.g., finance) have standards for handling outliers in range calculations.
When in doubt, visualize the data (e.g., box plots) to see how outliers affect the distribution.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of versiliasolutions.oneagency.co.