How to Git Clone: The Definitive Manual for Developers
Table of Contents
- The Complete Overview of How to Git Clone
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: What’s the difference between `git clone` and `git init`?
- Q: Can I clone a repository without internet access?
- Q: How do I clone a specific branch?
- Q: Why does `git clone` fail with "Permission denied" for SSH?
- Q: What does `--depth 1` do in `git clone`?
- Q: How can I exclude certain files from a clone?
- Q: Is `git clone --mirror` different from a regular clone?
Git remains the backbone of modern collaboration in software development, and understanding how to git clone is foundational for any developer. The command isn’t just about copying code—it’s the gateway to participating in open-source projects, syncing team workflows, or restoring lost work. Yet, despite its ubiquity, many developers overlook nuanced aspects of the process, from authentication pitfalls to branch handling. Whether you’re cloning a public repository for the first time or optimizing a CI/CD pipeline, the mechanics of `git clone` demand attention to detail.
The simplicity of the command belies its complexity. A single `git clone` can trigger a cascade of operations: fetching remote references, initializing a local repository, and setting up tracking branches—all while silently resolving dependencies. Missteps here, such as ignoring shallow clones or failing to configure SSH, can derail projects before they begin. Developers who master this process gain not just efficiency, but the ability to troubleshoot when others might abandon a repository as "broken."
###

The Complete Overview of How to Git Clone
The `git clone` command is the first step in engaging with any Git-managed project, but its execution varies based on context. At its core, it creates a full copy of a remote repository—including all branches, tags, and commit history—while establishing a local connection to the original. This operation is atomic in nature: it either succeeds completely or fails, leaving no partial state. For teams, this means cloning a repository is both a collaborative ritual and a technical checkpoint, ensuring every developer starts from the same baseline.Understanding how to git clone effectively requires recognizing three layers of operation: the command itself, the underlying Git protocols (HTTP/SSH), and the local repository structure it creates. Each layer introduces variables—such as authentication methods, repository size, or branch strategies—that can alter the outcome. For instance, cloning a monorepo with thousands of commits may require adjustments to memory limits or fetch depth, while a lightweight fork might benefit from `--depth` to reduce bandwidth. The command’s flexibility is its strength, but this also means blind execution can lead to inefficiencies or security risks.
###
Historical Background and Evolution
Git’s design philosophy, rooted in Linus Torvalds’ 2005 implementation, prioritized speed and data integrity over user-friendly abstractions. The `clone` command emerged as a direct response to the need for distributed version control, where developers frequently worked offline or across unreliable networks. Early versions of Git treated cloning as a brute-force operation, mirroring the entire repository history to ensure no data loss—a trade-off that became less critical as hardware improved.Over time, optimizations like partial clones (introduced in Git 2.25) and sparse checkouts allowed developers to selectively fetch only necessary files, making how to git clone more adaptable to large-scale projects. These advancements reflected a shift toward efficiency without sacrificing Git’s core principles. Today, the command supports features like `--filter=blob:none`, which excludes binary files during initial cloning, reducing transfer times by up to 90% for certain repositories. This evolution underscores Git’s ability to balance performance with robustness.
###
Core Mechanisms: How It Works
When you execute `git clone`, Git initiates a handshake with the remote server using either HTTP/HTTPS or SSH, depending on the repository’s configuration. The server responds with a list of all refs (branches, tags) and their associated objects, which Git then downloads in a specific order: annotated tags first, followed by commit objects, trees, and blobs. This sequential fetching ensures that each object’s dependencies are resolved before use, preventing corruption.The local repository is initialized with a `.git` directory containing configuration files, hooks, and a `config` file that links to the original remote. Crucially, `git clone` does not execute any hooks or initialize working directories for submodules by default—these must be explicitly triggered with `--recurse-submodules` or `git submodule update`. This modular approach allows developers to customize the cloning process, such as excluding certain branches with `--branch` or limiting history with `--depth`.
###
Key Benefits and Crucial Impact
The ability to replicate a remote repository instantly transforms how teams collaborate. For open-source contributors, how to git clone a project is the first step toward submitting fixes or enhancements, while enterprises use it to onboard developers to proprietary codebases without exposing internal networks. The command’s reliability also extends to disaster recovery: cloning a backup repository can restore lost work with minimal effort.Beyond functionality, `git clone` embodies Git’s decentralized ethos. Unlike centralized systems where a single server failure halts access, Git repositories are self-contained. This resilience is critical in environments with intermittent connectivity or strict firewall rules, where cloning can proceed even when direct access to the original server is later restricted.
"Git clone isn’t just copying files—it’s establishing a bidirectional relationship between your local work and the collective knowledge of a project’s history." — Linus Torvalds (Git Creator, 2018)
Major Advantages
- Atomic Operations: The clone completes in one step, avoiding partial states that could corrupt the repository.
- Protocol Flexibility: Supports SSH (secure), HTTPS (easy setup), and Git (native) protocols, adapting to infrastructure constraints.
- Branch Preservation: All remote branches are cloned by default, enabling immediate experimentation without manual setup.
- History Integrity: The full commit graph is replicated, ensuring tools like `git blame` and `git log` function identically on all clones.
- Extensibility: Flags like `--no-checkout` or `--template` allow customization for CI/CD pipelines or large-scale deployments.
Comparative Analysis
| Feature | How to Git Clone | Alternative (e.g., `svn checkout`) |
|---|---|---|
| Protocol Support | SSH, HTTPS, Git (native) | HTTP/HTTPS only (SVN) |
| History Depth | Full or shallow (`--depth`) | Full history only |
| Submodule Handling | Requires `--recurse-submodules` | External dependency management |
| Partial Clones | Supported via `--filter` or `--sparse` | Not supported |
Future Trends and Innovations
The next generation of `git clone` will likely focus on reducing latency for large repositories. Projects like Git’s "partial clone" (experimental as of 2023) promise to fetch only the branches or files a developer needs, cutting initial clone times from hours to minutes. Additionally, integration with tools like Git LFS (Large File Storage) will become seamless, allowing binary assets to be cloned on-demand rather than upfront.Another frontier is AI-assisted cloning, where tools analyze repository metadata to suggest optimized clone strategies—such as prioritizing frequently accessed branches or excluding irrelevant history. While speculative, these advancements could redefine how developers interact with repositories, blurring the line between `git clone` and a contextualized workspace setup.
###
Conclusion
Mastering how to git clone is more than memorizing a command—it’s about understanding the infrastructure that enables modern software development. The process touches on authentication, network protocols, and repository design, each of which can be tuned for performance or security. For developers, this knowledge translates to fewer debugging sessions and smoother collaboration.As Git continues to evolve, the principles behind `git clone` will remain constant: reliability, flexibility, and decentralization. The tools may change, but the core mechanism—replicating a project’s history and state—will endure as the foundation of version control.
###
Comprehensive FAQs
Q: What’s the difference between `git clone` and `git init`?
A: `git clone` creates a local copy of a remote repository, including all branches and history, while `git init` only initializes an empty local repository. Cloning is for joining existing projects; initializing is for creating new ones.
Q: Can I clone a repository without internet access?
A: No. `git clone` requires a live connection to the remote server to fetch objects. However, you can later work offline after the initial clone, provided no new commits are pushed.
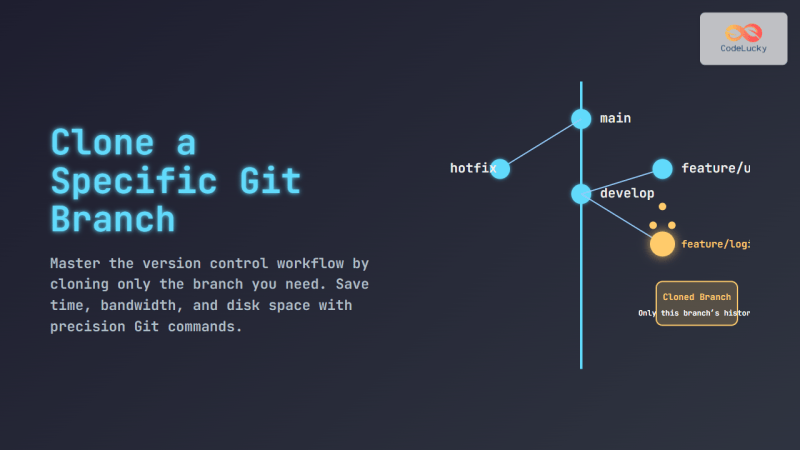
Q: How do I clone a specific branch?
A: Use `git clone -b
Q: Why does `git clone` fail with "Permission denied" for SSH?
A: This typically occurs due to missing SSH keys or incorrect permissions. Ensure your public key is added to the remote server’s `authorized_keys` file and that the repository URL uses `git@github.com:user/repo.git` (not HTTPS).
Q: What does `--depth 1` do in `git clone`?
A: It creates a shallow clone, fetching only the latest commit and its immediate parents. This is useful for CI/CD pipelines where full history isn’t needed, but note that future pulls will require `--depth` to maintain the shallow state.
Q: How can I exclude certain files from a clone?
A: Use `--filter=blob:none` to skip downloading binary files initially, or `--sparse` to check out only specific paths. For permanent exclusions, configure `git config --global core.sparseCheckout` post-clone.
Q: Is `git clone --mirror` different from a regular clone?
A: Yes. A mirror clone (`--mirror`) creates a full replica of the remote repository, including all refs and configurations, making it suitable for backups or acting as a secondary remote. Regular clones omit refs not checked out locally.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of versiliasolutions.oneagency.co.