How Big-O Notation Reshapes Problem-Solving in Tech
Table of Contents
- The Complete Overview of Big-O Notation
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why is big-O notation called "Big-O" and not something else?
- Q: Can big-O notation describe average-case performance?
- Q: How does big-O relate to real-world hardware constraints?
- Q: Are there algorithms with no big-O classification?
- Q: How can I improve my intuition for big-O analysis?
The language of efficiency in computer science isn’t written in lines of code—it’s distilled into symbols. Big-O notation, the shorthand for describing algorithmic performance, is the invisible framework that separates scalable systems from those that collapse under load. When developers discuss whether a function will run in milliseconds or minutes, they’re implicitly referencing this mathematical convention. It’s the reason why sorting a million records might take seconds with one approach but hours with another, and why tech giants obsess over optimizing their backends to handle exponential growth.
Yet for all its ubiquity, big-O notation remains a mystery to many outside theoretical circles. It’s not just about counting operations; it’s a lens through which entire industries—from fintech to autonomous vehicles—evaluate trade-offs between speed, memory, and cost. The notation’s elegance lies in its abstraction: it strips away hardware specifics to reveal the fundamental limits of any computational problem. Whether you’re debugging a slow API or designing a neural network, understanding how to analyze and communicate algorithmic complexity is the difference between a prototype and a production-ready solution.
The notation’s power stems from its simplicity. A single letter—O—encapsulates the worst-case scenario of an algorithm’s behavior as input size grows. But beneath that simplicity hides a rigorous framework that has evolved alongside computing itself. From Knuth’s early formalizations to modern applications in quantum algorithms, big-O notation has become the lingua franca of performance analysis. Its principles aren’t just academic; they’re the bedrock of scalable infrastructure, influencing everything from search engines to blockchain protocols.

The Complete Overview of Big-O Notation
Big-O notation is the theoretical scaffolding that allows engineers to reason about scalability without getting bogged down in machine-specific details. At its core, it’s a way to describe how an algorithm’s runtime or space requirements grow relative to the size of its input. The notation isn’t about exact measurements—it’s about asymptotic behavior, capturing trends as inputs approach infinity. This abstraction is what makes it indispensable: whether you’re optimizing a sorting algorithm for a supercomputer or a mobile app’s database queries, the principles remain the same.The notation’s strength lies in its generality. It doesn’t care about the programming language, hardware architecture, or even the problem domain. A O(n log n) algorithm will always outperform O(n²) as datasets expand, regardless of whether it’s implemented in Python or Rust. This universality is why big-O has transcended academia to become a critical tool in interviews, system design, and performance tuning. Mastering it isn’t about memorizing symbols—it’s about developing an intuition for how different operations interact as scale increases.
Historical Background and Evolution
The origins of big-O notation trace back to 19th-century mathematics, where Paul Bachmann and later Edmund Landau used similar concepts to describe the growth rates of functions. However, its adoption in computer science is largely credited to Donald Knuth, who popularized the notation in his seminal 1976 work The Art of Computer Programming. Knuth’s formalization tied asymptotic analysis to practical algorithm design, demonstrating how theoretical insights could directly improve software efficiency. Before this, engineers relied on ad-hoc benchmarks or trial-and-error, often leading to inefficient implementations.The evolution of big-O notation paralleled the rise of computing itself. In the 1950s and 60s, as computers transitioned from room-sized mainframes to time-sharing systems, the need for efficient algorithms became urgent. Knuth’s work coincided with the development of sorting algorithms like Quicksort and Merge Sort, which were analyzed using big-O to prove their superiority over older methods like Bubble Sort (O(n²)). The notation also became a cornerstone of complexity theory, helping classify problems as tractable (e.g., O(n log n)) or intractable (e.g., NP-hard). Today, it’s a staple in undergraduate curricula, ensuring that every aspiring engineer understands the trade-offs between different approaches.
Core Mechanisms: How It Works
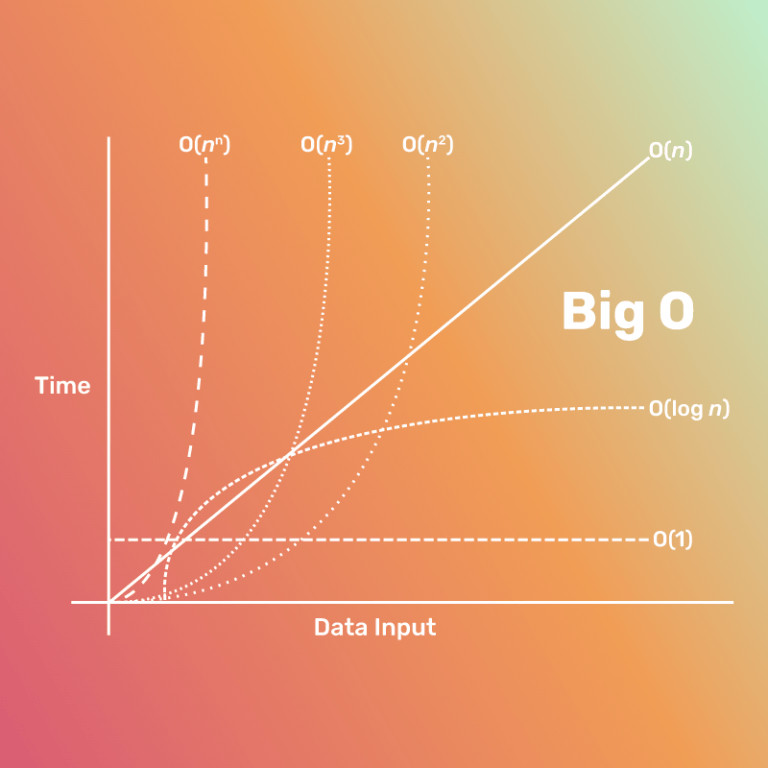
Big-O notation focuses on the upper bound of an algorithm’s growth rate, ignoring constants and lower-order terms. For example, an algorithm with a runtime of 3n² + 2n + 1 is classified as O(n²) because the n² term dominates as n grows large. This simplification is crucial: it allows engineers to compare algorithms at scale without worrying about minor optimizations. The notation uses letters to represent common growth rates—O(1) for constant time, O(log n) for logarithmic, O(n) for linear, and so on—each indicating how the runtime or space requirements expand with input size.The notation isn’t just about runtime; it also describes space complexity, such as O(n) for an array that doubles in size with each input. This dual application ensures that engineers can optimize both speed and memory usage. For instance, a hash table offers O(1) average-case lookups but may require O(n) space, while a binary search tree balances O(log n) operations with O(n) storage. The choice between these structures often hinges on understanding their big-O trade-offs in a given context.
Key Benefits and Crucial Impact
Big-O notation is more than a theoretical tool—it’s a practical compass for navigating the complexities of large-scale systems. In an era where applications handle petabytes of data, the difference between O(n) and O(n log n) can mean the difference between a system that runs in real-time and one that grinds to a halt. Tech companies like Google and Amazon use big-O analysis to design distributed systems that scale horizontally, while startups rely on it to avoid costly rework when user bases grow unexpectedly. The notation’s impact extends beyond software: it informs hardware design, network protocols, and even economic models of resource allocation.The notation’s value lies in its ability to standardize communication about performance. Without big-O, discussions about algorithmic efficiency would devolve into vague terms like "fast" or "slow," making collaboration nearly impossible. Instead, engineers can precisely articulate constraints—such as "this API must handle 10,000 requests per second with O(1) latency"—and build systems that meet those requirements. This precision is why big-O is taught alongside basic programming concepts: it’s the foundation of scalable, maintainable code.
"Big-O notation is the Rosetta Stone of computer science—it translates abstract problems into concrete performance guarantees." — Donald Knuth, in correspondence with ACM
Major Advantages
- Scalability Prediction: Big-O analysis reveals how an algorithm behaves as input size grows, allowing engineers to anticipate bottlenecks before they occur. For example, a O(n²) algorithm may work fine for 1,000 items but fail catastrophically at 1 million.
- Language Agnostic: The notation applies universally, regardless of whether code is written in JavaScript, Go, or Assembly. This makes it a reliable tool for cross-platform optimization.
- Trade-off Clarity: It quantifies the cost of optimizations, such as trading O(n) time for O(n) space in a dynamic programming solution, helping teams make informed decisions.
- Interview and Hiring Standard: Proficiency in big-O notation is a litmus test for algorithmic thinking in technical interviews, ensuring candidates can design efficient solutions under pressure.
- Hardware Independence: By abstracting away machine-specific details, big-O enables engineers to focus on problem-solving rather than hardware constraints, fostering innovation.
Comparative Analysis
| Notation | Characteristic Behavior |
|---|---|
| O(1) - Constant | Runtime remains unchanged regardless of input size (e.g., array indexing). Ideal for high-frequency operations like cache lookups. |
| O(log n) - Logarithmic | Growth slows as input size increases (e.g., binary search). Efficient for divide-and-conquer algorithms. |
| O(n) - Linear | Runtime scales directly with input size (e.g., linear search). Acceptable for small datasets but problematic at scale. |
| O(n²) - Quadratic | Runtime grows with the square of input size (e.g., Bubble Sort). Only viable for tiny inputs. |
Future Trends and Innovations
As computing paradigms shift—from classical to quantum and from centralized to distributed—the role of big-O notation is evolving. Quantum algorithms, for instance, challenge traditional complexity classes, with problems like Shor’s algorithm demonstrating exponential speedups over classical counterparts. Meanwhile, the rise of edge computing and IoT devices has renewed interest in O(1) and O(log n) optimizations to minimize latency in resource-constrained environments. The notation’s future may also incorporate probabilistic analysis (e.g., O(n) with high probability) to account for randomized algorithms in machine learning.Another frontier is the intersection of big-O with sustainability. As data centers consume vast energy, the environmental cost of inefficient algorithms is becoming a metric in its own right. Engineers are now considering "green complexity"—where big-O isn’t just about time but also about energy consumption. This shift reflects a broader trend: the notation’s principles are being repurposed to address real-world constraints beyond pure performance.
Conclusion
Big-O notation is the silent architect of modern computing, shaping everything from the apps on our phones to the infrastructure that powers global economies. Its ability to distill complex behaviors into simple symbols makes it one of the most powerful tools in a developer’s arsenal. Yet its true value lies not in the symbols themselves, but in the mindset they encourage: a relentless focus on efficiency, scalability, and trade-offs.For engineers, understanding big-O isn’t just about passing interviews or optimizing code—it’s about thinking critically about how systems will behave under stress. As technology advances, the notation’s relevance only grows, serving as a bridge between theoretical insights and practical solutions. Whether you’re debugging a latency issue or designing the next generation of AI, big-O notation remains the compass that guides you toward optimal performance.
Comprehensive FAQs
Q: Why is big-O notation called "Big-O" and not something else?
A: The term originates from the German word "Ordnung," meaning "order," which was used by Edmund Landau in the early 20th century to describe the growth rate of functions. Donald Knuth later popularized the term "Big-O" in computer science to emphasize the upper bound of complexity.
Q: Can big-O notation describe average-case performance?
A: No, big-O strictly describes the worst-case scenario. For average-case analysis, engineers use related notations like "Theta" (Θ) for tight bounds or "Omega" (Ω) for lower bounds. Average-case behavior is often context-dependent and harder to generalize.
Q: How does big-O relate to real-world hardware constraints?
A: Big-O abstracts away hardware specifics, but real-world performance depends on factors like CPU cache, parallelism, and memory bandwidth. For example, a O(n) algorithm might run faster than a O(n log n) algorithm on a GPU due to hardware optimizations, even though the asymptotic complexity suggests otherwise.
Q: Are there algorithms with no big-O classification?
A: Most practical algorithms fall into well-defined complexity classes, but some—like those involving chaotic systems or quantum randomness—defy traditional big-O analysis. These are typically analyzed using probabilistic or non-asymptotic methods.
Q: How can I improve my intuition for big-O analysis?
A: Start by practicing with simple loops and nested structures, then move to recursive algorithms. Use online tools like Big-O Cheat Sheets to visualize growth rates, and solve problems on platforms like LeetCode to see how complexity affects real-world performance.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of versiliasolutions.oneagency.co.