How to Execute an Effortless R Package Install in 2024
Table of Contents
- The Complete Overview of R Package Install
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Why does `install.packages()` fail with "package not available"?
- Q: How do I install an R package from a local file?
- Q: Can I install R packages without admin rights?
- Q: What’s the difference between `install.packages()` and `library()`?
- Q: How do I update all R packages at once?
- Q: Why does `install.packages()` take so long?
- Q: How do I install a package from a private Git repository?
- Q: What’s the best way to document installed packages for reproducibility?
The command `install.packages()` is the gateway to expanding R’s capabilities. Whether you’re integrating a new statistical model, visualizing complex datasets, or automating workflows, the R package install process is foundational. Yet, beneath its simplicity lies a system of repositories, dependencies, and versioning that demands precision—especially when errors like "package not available" or "conflicting dependencies" interrupt progress. These issues aren’t just technical hurdles; they reflect deeper questions about how R’s ecosystem manages growth while maintaining stability.
For data scientists, the R package install workflow is more than syntax—it’s a reflection of reproducibility. A single misconfigured dependency can cascade into failed analyses, forcing costly rework. The solution isn’t just memorizing commands but understanding the why behind them: why CRAN prioritizes certain packages, how Bioconductor curates domain-specific tools, or why `remotes::install_github()` bypasses traditional repositories. These nuances separate efficient practitioners from those stuck in debugging loops.
The stakes are higher than ever. As R’s user base grows—from academic researchers to enterprise data teams—the demand for seamless R package install processes has intensified. Cloud-based R environments, containerization, and automated CI/CD pipelines now intersect with traditional package management, creating a hybrid landscape where legacy commands must coexist with modern infrastructure.
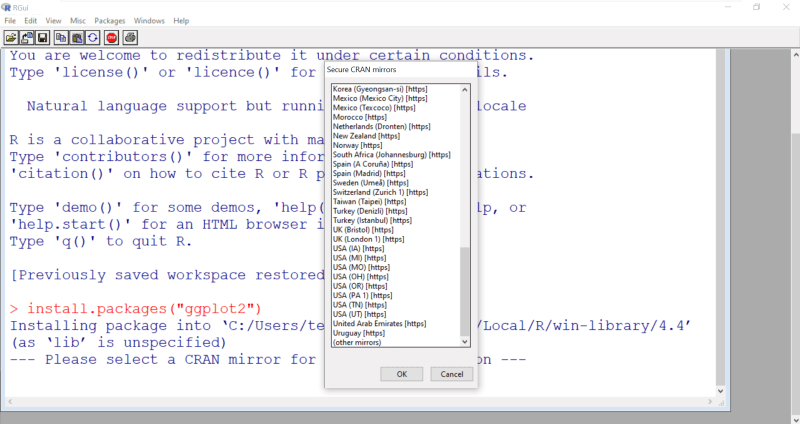
The Complete Overview of R Package Install
At its core, R package install refers to the process of downloading and integrating third-party libraries into your R environment. This isn’t limited to CRAN (Comprehensive R Archive Network); it includes Bioconductor, GitHub repositories, and private package archives. The primary function, `install.packages()`, serves as the default method, but alternatives like `devtools::install_github()` or `renv::restore()` cater to specific needs—whether you’re working with development versions, dependency-heavy projects, or offline setups.The mechanics extend beyond installation: package management in R involves dependency resolution, version conflicts, and environment isolation. Tools like `pacman`, `installr`, and `checkpoint` introduce layers of control, while `remotes` and `devtools` bridge the gap between CRAN and non-CRAN sources. Even the humble `library()` command relies on a successfully completed R package install to function, making this step non-negotiable for any R-based workflow.
Historical Background and Evolution
The R package install system traces its origins to the late 1990s, when R was still an academic project. Early package management was manual: users downloaded `.tar.gz` files from FTP servers and installed them via `R CMD INSTALL`. This ad-hoc approach worked for a small community but became unsustainable as R’s popularity surged. The creation of CRAN in 2000 marked a turning point, standardizing package distribution and introducing automated checks for quality and compatibility.By the 2010s, the ecosystem fragmented further. Bioconductor emerged for bioinformatics, GitHub became a hub for experimental packages, and tools like `devtools` democratized access to development versions. Today, the R package install landscape is a patchwork of repositories, each with its own governance model. CRAN remains the default due to its rigorous review process, while GitHub offers agility at the cost of stability. This evolution mirrors R’s broader journey from a statistical niche tool to a mainstream data science platform.
Core Mechanisms: How It Works
When you execute `install.packages("dplyr")`, R initiates a multi-step process. First, it queries CRAN’s mirrors to locate the package, downloading the latest stable version (or a specified version). The installer then checks for dependencies—`dplyr` requires `R (>= 3.0.0)` and packages like `R6`—and resolves them recursively. If dependencies conflict (e.g., two packages need incompatible versions of `tidyselect`), R halts installation unless you use `dependencies = FALSE` or specify a mirror with resolved conflicts.Under the hood, the process involves compiling C/C++ code (for performance-critical packages) and linking libraries. This is why some installations fail on Windows or macOS without RTools or Xcode Command Line Tools, respectively. The `install.packages()` function abstracts these complexities, but understanding them is critical for troubleshooting. For instance, knowing that `install.packages("package", repos = "https://cloud.r-project.org")` can bypass regional mirror issues saves hours of debugging.
Key Benefits and Crucial Impact
The R package install system is the backbone of R’s extensibility. Without it, users would be limited to base R functions—a scenario unimaginable for modern data science. Packages like `tidyverse`, `caret`, and `shiny` wouldn’t exist, and tasks from EDA to deployment would require custom code. The impact extends to collaboration: sharing analyses via reproducible environments (e.g., `renv`) relies on consistent R package install across teams.This ecosystem also drives innovation. Developers contribute packages to solve niche problems—whether it’s `sf` for geospatial data or `plumber` for APIs—creating a feedback loop where solutions become part of the standard toolkit. For organizations, the ability to install enterprise-grade packages (e.g., `MicrosoftML`, `dbplyr`) directly into R environments reduces the need for separate tools, streamlining workflows.
"The strength of R lies not in its core but in the packages built around it. The R package install process is how that strength is deployed." — Hadley Wickham, Creator of `tidyverse`
Major Advantages
- Access to Specialized Tools: CRAN hosts over 18,000 packages, covering everything from machine learning (`xgboost`) to web scraping (`rvest`). Installing these via `install.packages()` unlocks functionality without reinventing the wheel.
- Dependency Management: Tools like `remotes` and `packrat` handle complex dependencies automatically, reducing conflicts during R package install and ensuring reproducibility.
- Version Control: Specifying versions (e.g., `install.packages("ggplot2", version = "3.3.5")`) or using `renv` locks environments to exact package states, critical for collaborative projects.
- Performance Optimization: Packages like `data.table` or `arrow` compile native code during installation, delivering speedups that pure R cannot match.
- Community and Maintenance: CRAN’s review process ensures packages meet quality standards, while GitHub’s forks allow community-driven fixes—both critical for long-term R package install reliability.
Comparative Analysis
| Method | Use Case |
|---|---|
install.packages() |
Installing stable CRAN/Bioconductor packages with minimal dependencies. |
devtools::install_github() |
Testing development versions or private repositories (e.g., corporate R packages). |
renv::restore() |
Recreating exact project environments for reproducibility. |
installr::install.packages() |
Bypassing RStudio’s package manager for scripted installations (e.g., in CI/CD). |

Future Trends and Innovations
The R package install process is evolving with containerization and cloud computing. Tools like `rocker/r-ver` and Docker images allow users to pre-install packages in isolated environments, eliminating "works on my machine" issues. Meanwhile, platforms like Posit Cloud (formerly RStudio Cloud) integrate R package install directly into collaborative workflows, reducing friction for teams.Another trend is the rise of package "supermarkets"—repositories that aggregate CRAN, GitHub, and private packages under one interface (e.g., `install.packages("package", repos = "https://r-lib.github.io/packrat/")`). This simplifies multi-source installations but raises questions about governance. As R expands into industries like finance and healthcare, R package install will need to adapt to stricter compliance requirements, potentially introducing signed packages or audit trails for critical dependencies.
Conclusion
The R package install command is deceptively simple, but its implications are vast. It’s the bridge between R’s core functionality and the limitless possibilities of its ecosystem. Mastering it means understanding not just the syntax but the underlying infrastructure—why some packages fail to install, how to resolve conflicts, and when to deviate from CRAN. As R’s role in data science grows, so too will the sophistication of its package management tools, demanding that users stay ahead of the curve.For now, the principles remain constant: verify dependencies, choose the right repository, and document your environment. Whether you’re installing a single package or managing a complex project, the R package install process is your first step toward leveraging R’s full potential.
Comprehensive FAQs
Q: Why does `install.packages()` fail with "package not available"?
A: This typically occurs when the package isn’t on CRAN or your selected mirror. Solutions include:
- Using `repos = "https://cloud.r-project.org"` to bypass regional mirrors.
- For GitHub packages, switch to `devtools::install_github("user/repo").
- Checking the package name for typos or archived status (e.g., `archived = TRUE`).
Q: How do I install an R package from a local file?
A: Use `install.packages("path/to/package.tar.gz", repos = NULL)`. For `.zip` files, extract the `.tar.gz` first or use `install.packages(..., type = "source")` after unzipping.
Q: Can I install R packages without admin rights?
A: Yes. Use `lib = "~/R/library"` to specify a personal library directory. Example:
install.packages("dplyr", lib = "~/R/library")
This avoids system-wide permissions issues.
Q: What’s the difference between `install.packages()` and `library()`?
A: `install.packages()` downloads and compiles the package to your library, while `library()` loads it into your R session. Installing without loading is common for dependency-heavy projects.
Q: How do I update all R packages at once?
A: Use `update.packages(ask = FALSE, checkBuilt = TRUE)`. To update only certain packages, pass a vector:
update.packages(c("ggplot2", "tidyverse"), ask = FALSE)
Q: Why does `install.packages()` take so long?
A: Delays often stem from:
- Slow internet connections (try `repos = "https://cran.rstudio.com"` for faster mirrors).
- Compilation of C/C++ code (ensure RTools/Xcode is installed).
- Dependency resolution (use `dependencies = TRUE` explicitly).
Q: How do I install a package from a private Git repository?
A: Use `remotes::install_github()` with authentication:
remotes::install_github("org/repo", auth_token = "your_token")
For SSH, ensure your SSH key is added to GitHub.
Q: What’s the best way to document installed packages for reproducibility?
A: Use `renv::init()` to lock your environment, then share the `renv.lock` file. Alternatively, generate a list with:
installed.packages()[, "Package"]
and include it in project documentation.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of versiliasolutions.oneagency.co.